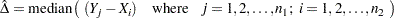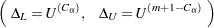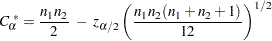안녕하세요 여러분,이 스레드에 대한 몇 가지 해결책을 제공해 드리고 싶습니다. @sseligman SAS JMP 고객 지원 (awesome!)에서 X 플랫폼에 의한 Fit Y 외의 Hodges-Lehmann 신뢰 구간을 계산하는 .jsl 스크립트를 제공했습니다.
알파 레벨을 간단히 수정하면 해당하는 단면 리미트를 계산할 수 있습니다. JMPs는 기본 양면 한계입니다. 또한이 스크립트는 이러한 비모수적인 한계를 계산하는 이점을 제공합니다 유무에 관계없이 JMP가 기본적으로 사용하는 소위 "연속성 보정"이며 SAS는 그렇지 않습니다. 예를 들어 그룹 1과 그룹 2의 두 그룹이 있고 기존 사양에 적용해야 할 변경 사항을 예측할 목적으로 위험 평가를위한 간격을 계산하는 경우에 특히 유용 할 수 있습니다 그룹 1의 경우, 그룹 2의 경우 똑같이 보수적 인 상태를 유지해야합니다. 물론 이것은 그룹 전체의 위치 차이에 통계적으로 감지 할 수있는 차이가 있음을 미리 보여줍니다 (그리고 그 차이는 실제적으로 중요합니다).
일반적으로 일면 간격의 경우 "α / 2"를 "α"로 바꿉니다. 따라서, 1면의 경우 신뢰도 = 1 - α. 양면 인 경우 신뢰도 = 1 - (α / 2).
마지막으로, 차이점의 순서를 변경하려면 (그리고 CI를 포함한 위치 차이에 대한 후속 계산) 스크립트의 아래 부분에서 "오름차순"을 "내림차순"으로 변경하기 만하면됩니다.
// Pick up distinct values
sortx = Sort Ascending( x );
여기에 전체 스크립트가 있으며 첨부 파일로 포함하고 있습니다.
// Main routine
MainNonParMCP=Function({},{default local},
 // Column dialog to get data values
 alpha=0.10;
 {alpha,ng, xdistinct, x, y}=GetDataMatrix(alpha);

 /* ---------------------------------------------------*/
 /* for each pair */
 OB1=NonparMCP(ng, xdistinct, x, y, alpha, method=1);
 /* for all pairs (Steel-Dwass) */
 OB2=NonparMCP(ng, xdistinct, x, y, alpha, method=2);
 /* comparisons with the control */
 OB3=NonparMCP(ng, xdistinct, x, y, alpha, method=3);

 /* ---------------------------------------------------*/
 /* Bonferroni for Joint Ranking */
 /* for each pair */
 OB4=BonferroniJointRanking(ng, xdistinct, x, y, alpha, method=1);
 /* for all pairs */
 OB5=BonferroniJointRanking(ng, xdistinct, x, y, alpha, method=2);
 /* comparisons with the control */
 OB6=BonferroniJointRanking(ng, xdistinct, x, y, alpha, method=3);

 New Window("Result",
  OutlineBox("Steel and Steel-Dwass",
   OB1,OB2, OB3
  ),
  OutlineBox("Bonferroni for Joint Ranking",
   OB4,OB5, OB6
  )
 )

);

//
// Invoke column data dialog box, and
// get data values from a data table.
//
GetDataMatrix = Function(
 {alpha},{default local},

 dt = Current Data Table();
 If( Is Empty( dt ),
  dt = Open()
 );
 If( Is Scriptable( dt )==0,
  Dialog( "Please open a data table before running this script" );
  Throw();
 );

 // Column Dialog
 dlg = Column Dialog(
  "Select X and Y Column",
  ycol = ColList( "Y, Continuous", DataType( numeric ), MinCol( 1 ), MaxCol( 1 ) ),
  xcol = ColList( "X, Nominal", MinCol( 1 ), MaxCol( 1 ) ),
  HList("Alpha : ",alpha =EditNumber(alpha))
 );

 // If canceled
 If( Arg( dlg[N Arg( dlg )] ) != 1,
  Dialog( "Canceled" );
  Throw();
 );
 // Make Data
 xx = Column( dt, dlg["xcol"] ) << GetAsMatrix;
 yy = Column( dt, dlg["ycol"] ) << GetAsMatrix;
 x = {};
 y = [];
 // Exclude missing values or excluded values
 For( i = 1, i <= N Row( yy ), i++,
  If( Excluded( Row State( i ) ) == 0 & Is Missing( xx[i] ) == 0 & Is Missing( yy[i] ) == 0,
   Insert Into( x, xx[i] );
   y |/= yy[i];
  )
 );
 // Pick up distinct values
 sortx = Sort Descending( x );

 /*change "Descending" to "Ascending" in the above line of code to change the order of the groups*/

 xdistinct = {};
 Insert Into( xdistinct, sortx[1] );
 For( i = 2, i <= N Items( sortx ), i++,
  If( sortx[i] != sortx[i - 1],
   Insert Into( xdistinct, sortx[i] )
  )
 );
 ng = N Items( xdistinct );

 If(IsMissing(dlg["alpha"])!=0,
  alpha=dlg["alpha"]
 );
 Eval List( {alpha, ng, xdistinct, x, y} );
);


// Wilcoxon tests and Hodges-Lehman confidence interval for two samples
Wilcoxon_HL=Function({y1,y2,q},{default local},
 n1=NRow(y1); /* Sample Size of Group 1 */
 n2=NRow(y2); /* Sample Size of Group 2 */
 n=n1+n2;
 r=RankingTie(y1|/y2);

 T1=Sum(r[1::n1]);
 T2=n*(n+1)/2-T1;
 diff=T2/n2-T1/n1;
 stderr=Stddev(r)*Sqrt(1/n1+1/n2);

 z=diff/stderr;
 If(diff>0,
  diffc=max(0,(T2-0.5)/n2-(T1+0.5)/n1),
  diffc=min(0,(T2+0.5)/n2-(T1-0.5)/n1)
 );

 zc=diffc/stderr;

 /* Hodges-Lehman: Point estimation and Confidence Interval */
 dvec=J(n1*n2,1,.);
 k=0;
 For(i=1,i<=n1,i++,
  For(j=1,j<=n2,j++,
   k++;
   dvec[k]=y2[j]-y1[i]
  )
 );
 dvec=Sort Ascending(dvec);

 /* Point Estimate */
 If(Mod(n1*n2,2)==1,
  HLEst= dvec[(n1*n2+1)/2]   ,
  HLEst= (dvec[(n1*n2)/2]+dvec[(n1*n2)/2+1])/2
 );

 /* Confidence interval without continuity correction */
 C = Floor( n1*n2/2 - q*Sqrt(n1*n2*(n1+n2+1)/12));
 If(C<1,
  L=.;
  H=.;
  ,
  L=dvec[C];
  H=dvec[n1*n2+1-C]
 );
 /* Confidence interval without continuity correction */
 Cc = Floor( n1*n2/2 -0.5 - q*Sqrt(n1*n2*(n1+n2+1)/12));
 If(Cc<1,
  Lc=.;
  Hc=.;
  ,
  Lc=dvec[Cc];
  Hc=dvec[n1*n2+1-Cc]
 );
 EvalList({diff,stderr,z,zc,HLEst,L,H,Lc,Hc});
);


//Nonparametric comparison
// Method==1 ... For each pair, without continuity correction
// Method==2 ... For all pairs, nonparametric Tukey based on pairwise ranking
//      "Steel-Dwass test"
// Mehtod==3 ... Comparison with the control, nonparametric Dunnett based on pairwise ranking
//      "Steel test"
NonparMCP=Function({ng, xdistinct, x, y, alpha, method},{default local},
 Result=[];
 g1Label={};
 g2Label={};

 n=J(NItems(xdistinct),1,0);
 For(i=1,i<=NItems(x),i++,
  For(j=1,j<=ng,j++,
   If(x[i]==xdistinct[j],
    n[j]++;
    Break()
   );
  )
 );
 /* In order to perform, Steel test (nonparametric Dunnett),
    we need to get sample size for each group*/
 If(method==3,
  ncont=n[1];
  nother=Matrix(n[2::NRow(n)]);
  rho=(1+ncont:/nother)^(-0.5);
 );
 /* Calculate Crit. value */
 If(
  method==1,
  q=NormalQuantile(1-alpha/2),
  method==2,
  q=Tukey HSD Quantile(1-alpha,ng,.),
  method==3,
  q=DunnettQuantile(1-alpha,Nrow(nother),df=.,rho);
 );
 /* Loop Start */
 For(i=1,i<=ng-1,i++,
  If(method==3&i>=2,Break());
  For(j=i+1,j<=ng,j++,
   gval1=xdistinct[i];
   gval2=xdistinct[j];
   n1=n[i];
   n2=n[j];
   y1=[];
   y2=[];
   For(k=1,k<=NRow(y),k++,
    If(
     x[k]==gval1, y1|/=y[k],
     x[k]==gval2, y2|/=y[k]
    )
   );
   // Caclulate z-value and CI */
   {diff,stderr,z,zc,HLEst,L,H,Lc,Hc}=Wilcoxon_HL(y1,y2,q);
   // Calculate p-values from z
   If(method==1,
    p=2*NormalDistribution(-Abs(z));
    pc=2*NormalDistribution(-Abs(zc));
    ,
    method==2,
    p=Tukey HSD P value(Abs(z),ng,.);
    pc=Tukey HSD P Value(Abs(zc),ng,.);
    ,
    method==3,
    p=Dunnett P Value(Abs(z),ng-1,.,rho);
    pc=Dunnett P Value(Abs(zc),ng-1,.,rho);
   );
   Insert Into(g1Label,Char(gval1));
   Insert Into(g2Label,Char(gval2));
   Result|/= (n1||n2||diff||stderr||z||p||zc||pc||HLEst||L||H||Lc||Hc);
  )
 );

 If(
  method==1, titleOB="Nonparametric Comparison for Each Pair",
  method==2, titleOB="Nonparametric Comparison for All Pairs (Steel-Dwass)",
  method==3, titleOB="Nonparametric Comparison for Each Pair (Steel)"
 );
 OB=OutlineBox(titleOB,
  TableBox(
   NumberColBox(Char(100*alpha)||"% Critical value",Matrix(q))
  ),
  TableBox(
   StringColBox("Group2",g2Label),
   StringColBox("v.s. Group1",g1Label),
   NumberColBox("n2", Matrix(Result[0,2])),
   NumberColBox("n1", Matrix(Result[0,1])),
   NumberColBox("Diff in Mean Rank", Matrix(Result[0,3])),
   NumberColBox("Std Err", Matrix(Result[0,4])),
   NumberColBox("Z", Matrix(Result[0,5])),
   NumberColBox("p", Matrix(Result[0,6]),<<SET format="">=2,Break());
  For(j=i+1,j<=ng,j++,
   gval1=xdistinct[i];
   gval2=xdistinct[j];
   n1=n[i];
   n2=n[j];
   stderr=STotal*Sqrt(1/n1+1/n2);
   diff=T[j]/n2-T[i]/n1;
   z=diff/stderr;
   If(diff>0,
    diffc=Max(0,(T[j]-0.5)/n2-(T[i]+0.5)/n1),
    diffc=Min(0,(T[j]+0.5)/n2-(T[i]-0.5)/n1)
   );
   zc=diffc/stderr;
   If(method==1,
    p=2*NormalDistribution(-Abs(z));
    pc=2*NormalDistribution(-Abs(zc));
    ,
    method==2,
    p=Min(1,2*ng*(ng-1)/2*NormalDistribution(-Abs(z)));
    pc=Min(1,2*ng*(ng-1)/2*NormalDistribution(-Abs(zc)));
    ,
    method==3,
    p=Min(1,2*(ng-1)*NormalDistribution(-Abs(z)));
    pc=Min(1,2*(ng-1)*NormalDistribution(-Abs(zc)));
   );
   Insert Into(g1Label,Char(gval1));
   Insert Into(g2Label,Char(gval2));
   Result|/= (n1||n2||diff||stderr||z||p||zc||pc);
  )
 );
 If(
  method==1, titleOB="Nonparametric Comparison for Each Pair (without adjustment for Joint Ranking)",
  method==2, titleOB="Nonparametric Comparison for All Pairs (Bonferonni for Joint Ranking)",
  method==3, titleOB="Nonparametric Comparison for Each Pair (Bonferonni for Joint Ranking)"
 );
 OB=OutlineBox(titleOB,
  TableBox(
   StringColBox("Group2",g2Label),
   StringColBox("v.s. Group1",g1Label),
   NumberColBox("n2", Matrix(Result[0,2])),
   NumberColBox("n1", Matrix(Result[0,1])),
   NumberColBox("Diff in Mean Rank", Matrix(Result[0,3])),
   NumberColBox("Std Err", Matrix(Result[0,4])),
   NumberColBox("Z", Matrix(Result[0,5])),
   NumberColBox("p", Matrix(Result[0,6]),<<SET format=""></SET></SET>
마지막으로, 다음 사항을 지적하는 것이 중요하다고 생각합니다. 이것은 개별적인 문제이기 때문에 이러한 정확한 신뢰 한계에 대한 신뢰도 계수는 정확하게는 아닙니다.  하지만 적어도 . 따라서 이러한 신뢰 한계는 보수적입니다.